In this article
TL;DR: Google Cloud’s London region, europe-west2, had a multi-service outage on October 20 that hit dozens of services, including Compute Engine, Cloud Run, Cloud SQL, Cloud Storage, GKE and BigQuery. Google’s full incident report, posted October 27, says a utility cable fault cut power to the data center behind zone europe-west2-b while one of its two power feeds was already switched off for repairs, and a misconfigured controller never told the backup generators to start. When the batteries ran out, the zone’s data halls lost power. Google now dates the impact from 23:00 to 05:08 US/Pacific (06:00 to 12:08 UTC, 2:00 to 8:08 p.m. Manila), 6 hours and 8 minutes, and says zones europe-west2-a and -c were also hit by a surge of failover demand and by control-plane calls to the offline zone. If you run anything in europe-west2, check whether your failover actually worked, keep your logs for any SLA claim, and give the services you can’t lose a copy outside the region.
Update, Oct 29, 2026, 10:30 p.m. Manila: Google’s full incident report explains the outage. Google posted its full incident report on the incident page on October 27, 2026, at 08:13 PDT (11:13 p.m. Manila), replacing a preliminary report from October 22. We’ve updated the summary, cause, status and advice on this page. In our own words, here is what the report says:
- Root cause: The data center that hosts zone europe-west2-b normally runs on two utility feeds, A and B. Feed B had been switched off and locked out for repairs after problems found during a quarterly generator load test on October 14, so feed A carried the whole site. At 22:53 PDT on October 19 (1:53 p.m. Manila on October 20), an underground cable fault on the utility network outside the facility cut feed A. The backup generators should have started, but the dual-redundant programmable logic controllers (PLCs) that start them were wired to sense voltage upstream of the opened feed B breaker. Their logic also didn’t check whether that breaker was open. They saw live voltage there, concluded a healthy utility source was available, and never sent a start command. The site’s UPS batteries, which Google says give 5 minutes of runtime, carried the load until they ran out, and the data halls lost power completely. A remote load transfer through the PLC was blocked, so the on-site team switched the facility to a standby utility connection by hand.
- Timeline: Impact began at 23:00 PDT (2:00 p.m. Manila) when the batteries were exhausted, and Google’s monitoring alerted engineers at 23:04 PDT. Standby utility power was restored at 23:54 PDT and reached the data halls at 00:20 PDT on October 20 (3:20 p.m. Manila). Storage devices that had shut down uncleanly then needed a long recovery before Google let traffic back in. Google says its services and APIs were fully available again at 04:11 PDT (7:11 p.m. Manila), though some Compute Engine VMs weren’t yet; creation of new VMs resumed at 04:46 PDT, and by 05:08 PDT (8:08 p.m. Manila) 99.5% of Compute Engine VMs were healthy. Google’s incident page now gives the incident as 23:00 to 05:08 PDT, replacing the 23:08 start and 07:00 end it showed on October 20.
- Impact beyond one zone: Resources that lived only in europe-west2-b, such as VMs, zonal persistent disks, zonal GKE clusters, non-HA Cloud SQL instances and read replicas, basic AlloyDB primaries and single-cluster Bigtable instances, were unreachable. Google says that is how zonal resources are designed to behave, and that Compute Engine customers have to provision their own cross-zone failover. Zones europe-west2-a and -c were also affected, by a sudden surge of failover demand that used up compute capacity and by control-plane calls that waited on the offline zone. Google says some failovers failed because of capacity limits and storage replication problems, and that customers couldn’t create, update or delete some regional resources while it lasted. It found no impact outside europe-west2. The report’s product list also adds Dialogflow CX, Google SecOps and Looker Studio.
- Remediation: Google says the PLCs were reconfigured and validated on October 20 and again on October 26, generator load-transfer tests were run on both days, and the emergency operating procedure was rewritten (completed October 26). Google also says on-site staff now practice it twice per shift, an item it marks completed on October 24. Still open, with Google’s own target dates: repair of the feed A cable by October 30, a return to both utility feeds and a full generator test with them by October 31, a PLC code review by October 31, a check of PLC configurations at all its sites with similar setups by November 15, and a freeze on planned maintenance at similar sites with tighter change approvals by October 30. On the cloud side, Google plans an automated alert-to-communication mechanism for incidents that hit a location, and wider platform testing for infrastructure-level events. The report gives no dates for those two.
What this means for you: Our read: a regional service isn’t a guaranteed escape hatch when a whole zone drops. Google’s report says failovers into the other London zones ran into capacity limits and that creating or changing some regional resources failed. Our tip: if a service must stay up, run its standby copy before you need it rather than planning to create one during an outage, and keep a copy outside the region for the one or two services you can’t do without. If you plan an SLA claim, the report gives you Google’s official start and end times to cite.
Update, Oct 20, 2026, 10:25 p.m. Manila: Google ended the incident at 07:00 PDT (14:00 UTC) and posted a final update at 07:03 PDT; we’ve updated the headline, status and advice. An earlier version quoted Hostinger’s 11:42 UTC update saying its services were available again; Hostinger has since reworded that entry, and we now quote its 13:45 UTC update.
Update, Oct 20, 2026, 10:50 p.m. Manila: We added Hostinger’s 14:37 UTC update saying a fix has been pushed, and its 14:40 UTC update marking the incident resolved.
What happened
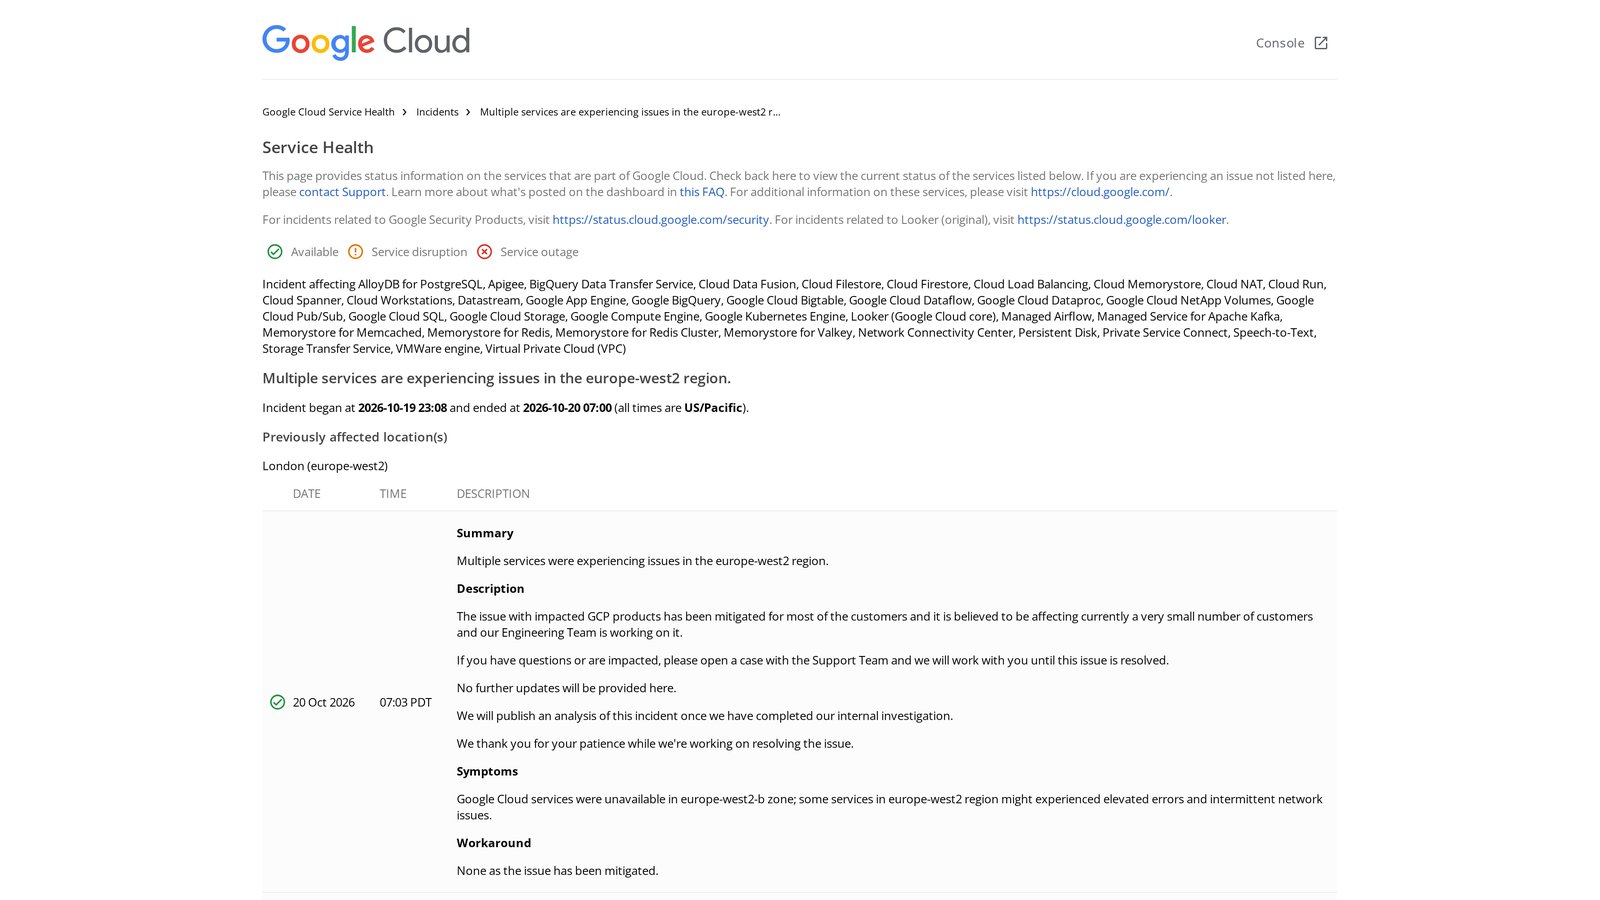
Google’s public incident said it was “experiencing an issue with multiple services in europe-west2 beginning on Monday, 2026-10-19 23:08 PDT.” That’s 06:08 UTC on Tuesday, October 20, or 2:08 p.m. in Manila. Google’s October 27 report now puts the start of impact at 23:00 PDT (2:00 p.m. Manila). Google first posted the incident on its public status page at 08:35 UTC (4:35 p.m. Manila).
- Symptoms: Google now describes them in the past tense: “Google Cloud services were unavailable in europe-west2-b zone; some services in europe-west2 region might experienced [sic] elevated errors and intermittent network issues.” Google’s earlier updates described “elevated errors and intermittent network failures in europe-west2 region.”
- Where: London (europe-west2) is the only location listed, now as previously affected. Google says the outage itself was “within europe-west2-b zone.”
- Status: Ended. Since Google posted its full report, its page says the “Incident began at 2026-10-19 23:00 and ended at 2026-10-20 05:08 (all times are US/Pacific),” which is 06:00 to 12:08 UTC, or 2:00 to 8:08 p.m. Manila, and it lists London (europe-west2) under “Previously affected location(s).” On October 20, the page showed a 23:08 start and a 07:00 end. Google’s final update, at 07:03 PDT (14:03 UTC, 10:03 p.m. Manila), says “The issue with impacted GCP products has been mitigated for most of the customers and it is believed to be affecting currently a very small number of customers and our Engineering Team is working on it.” It adds: “If you have questions or are impacted, please open a case with the Support Team and we will work with you until this issue is resolved,” and “No further updates will be provided here.” Google’s previous update, at 05:44 PDT (12:44 UTC), said it was “seeing the recovery of services for most workloads in europe-west2 as of Tuesday, 2026-10-20 05:10 PDT” (12:10 UTC, 8:10 p.m. Manila). Google’s page gives all times in US/Pacific.
- Workaround: Google now says “None as the issue has been mitigated.” During the outage, its workaround was: “If feasible, the impacted customer may try to migrate their workload impacted to another available location (zone or region).”
- Cause: Google has said “A power event caused an outage within europe-west2-b zone.” It first mentioned the power event in its 04:12 PDT update (11:12 UTC, 7:12 p.m. Manila), and repeated it at 04:58 PDT. Its October 27 full incident report gives the full explanation: a utility cable fault while one power feed was down for repairs, plus a generator controller misconfiguration (see the October 29 update above). Separately, Hostinger, which runs its control panel on Google Cloud, said on its own status page earlier that “Google notified us the outage was caused by a power failure at one of their data centers.” That’s Hostinger’s account; Google’s incident page doesn’t say it.
Affected products, per Google: AlloyDB for PostgreSQL, Apigee, BigQuery Data Transfer Service, Cloud Data Fusion, Cloud Filestore, Cloud Firestore, Cloud Load Balancing, Cloud Memorystore, Cloud NAT, Cloud Run, Cloud Spanner, Cloud Workstations, Datastream, Google App Engine, Google BigQuery, Google Cloud Bigtable, Google Cloud Dataflow, Google Cloud Dataproc, Google Cloud NetApp Volumes, Google Cloud Pub/Sub, Google Cloud SQL, Google Cloud Storage, Google Compute Engine, Google Kubernetes Engine, Looker (Google Cloud core), Google Cloud Composer (Managed Airflow), Managed Service for Apache Kafka, Memorystore for Memcached, Memorystore for Redis, Memorystore for Redis Cluster, Memorystore for Valkey, Network Connectivity Center, Persistent Disk, Private Service Connect, Speech-to-Text, Storage Transfer Service, VMware Engine and Virtual Private Cloud (VPC). Google’s 02:24 and 04:00 PDT updates noted that “Looker Studio is not impacted by this outage”; its four later updates don’t repeat that note, and Google’s October 27 incident report lists Looker Studio among the services that were affected.
Even if you don’t use Google Cloud
You may still be affected through a vendor. Hostinger said on October 20 that its dashboard, service API, Website Builder, Kodee and checkout were unavailable. In an update at 13:45 UTC (9:45 p.m. Manila), Hostinger said “Hostinger Dashboard and the service API are not fully available yet,” that “Some users can’t log in to Hostinger Dashboard, and hosting plans and their settings can’t be managed at the moment,” and that “Websites hosted with Hostinger are not affected and continue to work normally.” Hostinger has also changed the wording of its 11:42 UTC update, which had said a fix was applied and its services were available again; that entry now carries the same “not fully available yet” text. In an update at 14:37 UTC (10:37 p.m. Manila), Hostinger said: “A fix has been pushed and we are now monitoring the results. Hostinger Dashboard, API and hPanel should now be working as expected. We will provide another update when needed. We apologize for the inconvenience caused.” Three minutes later, at 14:40 UTC (10:40 p.m. Manila), Hostinger marked the incident resolved, saying: “The issue has been fixed, everything is operating as expected.” Other software you use may run in the same region. If a tool stops working today, check that vendor’s own status page before you start troubleshooting your side. We’ve seen this kind of vendor dependency before with ConnectWise’s Cloud Backup suspension, where customers could only wait for the provider.
How to tell if you’re affected
- Check where your resources run. Zones in London are named
europe-west2-a,-band-c. Google says the outage was withineurope-west2-b, and that some services in the europe-west2 region saw elevated errors. If none of your projects use europe-west2, this incident shouldn’t touch you directly. - Open the Service Health dashboard in the Google Cloud console. Google calls Personalized Service Health “your primary source for service disruptions relevant to you,” and it shows the incidents tied to your own projects. A Google Cloud support reply on X pointed a customer there for updates, too.
- If you can’t sign in, use the public page. Google’s docs say the public Google Cloud Service Health page at status.cloud.google.com needs no login and is the fallback when the console view isn’t available. It also has an RSS feed.
What to do now
- Check that your services came back. Google says most customers are no longer affected. Look at your own error rates, queues and scheduled jobs in europe-west2, and restart anything that got stuck. If you failed over to a standby region, plan the move back carefully rather than rushing it.
- Don’t rush to move a database. In our view, copying a live database to a new region during or right after an incident, without a tested replica, risks losing recent writes or ending up with two copies that disagree. If your data is only in London and it’s working again, check it for gaps before you change anything.
- Tell your customers. Post a short note on your site or status page: what was affected, that the cause was a Google Cloud regional incident, and whether everything is back.
- Still affected? Open a support case. Google’s final status update, at 07:03 PDT on October 20, told impacted customers to “open a case with the Support Team,” and its October 27 report says customers still having VM problems were directed to file a support case. Its docs say customers with Premium, Enhanced or Standard Support can create a support case and link it to a known issue.
- Keep a record. Save your error logs, alert times and the times your service was down. You’ll need them for an SLA claim.
What to set up after
- Claim SLA credits on time. Each Google Cloud product has its own SLA. To get a credit, you have to notify Google technical support yourself: within 60 days for Compute Engine, and within 30 days for Cloud Run and Cloud SQL, according to those products’ SLAs. Compute Engine and Cloud Run also require “log files showing Downtime Periods and the date and time they occurred,” and the credit is applied to future use, not paid out. SLAs exclude errors “caused by factors outside of Google’s reasonable control,” among others. Check the SLA for each product you use on Google’s SLA list.
- Set up Service Health alerts. In the Service Health dashboard, “Create Alert Policy” offers ready-made templates for new and updated incidents. You need the Service Health API enabled and a Cloud Monitoring notification channel for where alerts go.
- Decide what needs a second region. Spreading across zones protects you from a single-zone failure. Google says this outage was within one zone, europe-west2-b, but it listed the whole London region as the affected location and says some services in the region saw elevated errors. So a copy in another region is the safer bet for services that must stay up. Pick the one or two services your business can’t be without, and plan a second region just for those.
- Read Google’s incident report. Google published its full incident report on October 27, 2026, on the same incident page (summarized in the October 29 update above). Its docs say it publishes a public incident report after broad, severe incidents. Google lists several fixes as still open, with target dates from October 30 to November 15; we’ll note it here if Google changes the report.
Sources & method
Sources
- Google Cloud Service Health, incident “Multiple services are experiencing issues in the europe-west2 region” (also in incidents.json), including Google’s full incident report, posted October 27, 2026, at 08:13 PDT, and its preliminary incident report of October 22, 2026
- Google Cloud on X (@googlecloud), support reply pointing to Personalized Service Health, Oct 20, 2026
- Hostinger status page, incident “Hostinger Dashboard Service API Issue”
- Google Cloud docs, “Google Cloud incident communication”
- Google Cloud docs, “Use Google Cloud Service Health as a fallback”
- Google Cloud docs, “Quickstart: Set up an alert” (Personalized Service Health)
- Google Cloud, Compute Engine SLA, Cloud Run SLA and Cloud SQL SLA, and the list of Google Cloud SLAs
- Google Cloud docs, “Regions and zones”
Method. Last checked October 29, 2026, at 10:00 p.m. Manila time (14:00 UTC), against Google’s incident page and its incidents.json feed, which carry the October 27 full incident report (posted 08:13 PDT, 15:13 UTC) and show the incident as 23:00 to 05:08 PDT. The October 29 update summarizes that report in our own words; root cause, timeline, impact, remediation items and target dates are Google’s. The October 20 sections were checked at 10:49 p.m. Manila on October 20 against Google’s incident page as it stood then (ended at 07:00 PDT, final update at 07:03 PDT, 14:03 UTC) and Hostinger’s 14:37 and 14:40 UTC updates. Times, products, symptoms and Google quotes come from Google’s incident page, report and docs; the “power failure at one of their data centers” wording and the state of Hostinger’s services are Hostinger’s statements and are labeled as such. Manila and UTC times are converted from the Pacific times Google publishes. The advice on databases, standby copies and second regions is our own judgment. No affiliate links on this page. How we work.
Spotted an error? See our corrections policy and tell us.